ournews.aiNews in the AI era.

Live news

Vera Rubin delivers up to 2× GB300’s training performance per GPU in NVIDIA’s MLPerf Training 6.1 results; its DeepSeek-V3 run scaled from 256 to 1,024 GPUs at about 97% efficiency. These are benchmark results, not an across-the-board speedup.
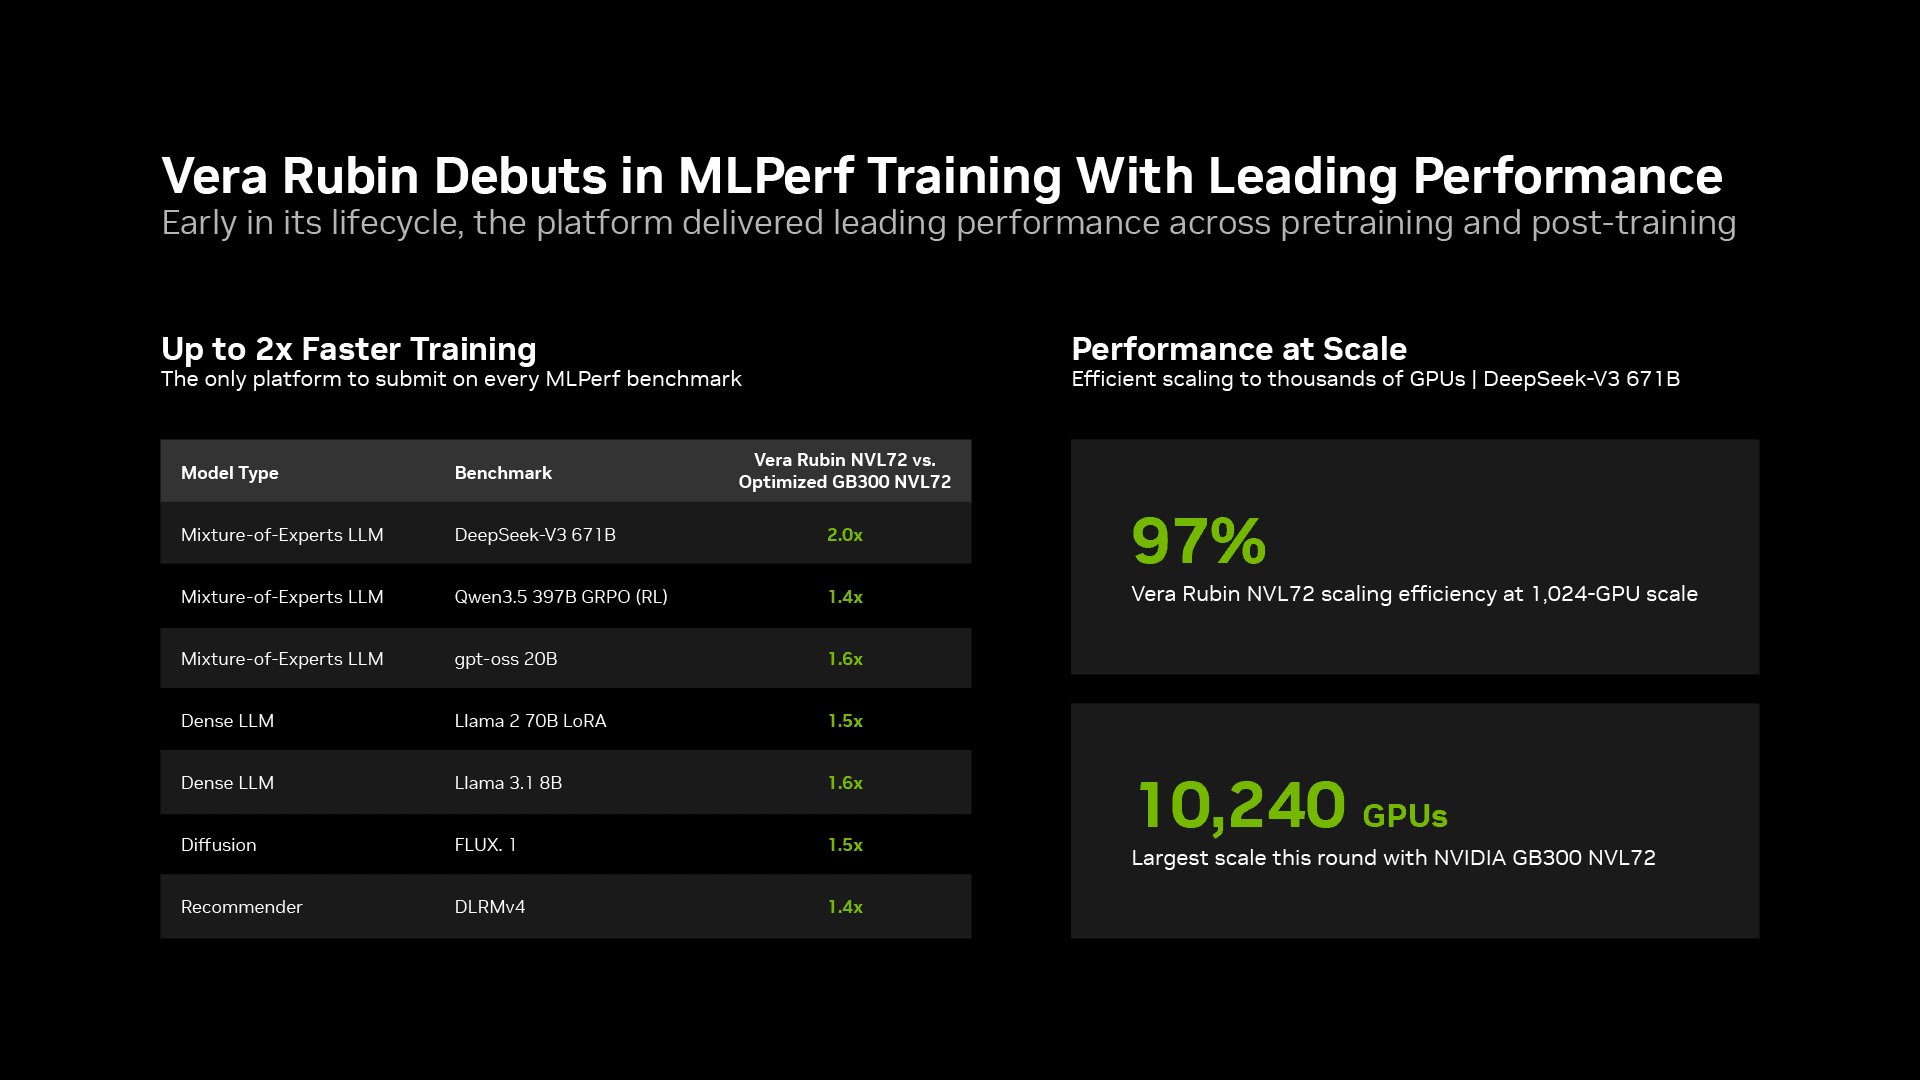
NVIDIA’s published MLPerf Training 6.1 performance chart from its November 16 Vera Rubin benchmark report. Vendor-presented benchmark comparison.

Published

NVIDIA / MLPerf Training 6.1 results ↗ · Source dated

—
Browse all Live updates · Read Features

Vera Rubin delivers up to 2× GB300’s training performance per GPU in NVIDIA’s MLPerf Training 6.1 results; its DeepSeek-V3 run scaled from 256 to 1,024 GPUs at about 97% efficiency. These are benchmark results, not an across-the-board speedup. · ournews.ai